Wednesday, July 20, 2011

Winsteps - Score Distributions

                                                             30

Winsteps requires score distributions to be very similar to fit the Rasch model when equating. You can do two things to a distribution of scores. You can shift the location of the distribution by subtracting from or adding a constant to each measure, or you can stretch or shrink the distribution by multiplying or dividing with a constant. Winsteps uses one or both of these adjustments when equating.

It is impractical, impossible, to have one set of students mark answers to all of the questions needed for a test bank on one test. This problem is solved, in theory, by administering several tests. Each test contains a set of common items. In theory, these common items will be equally difficult on every test.

Score distributions have many statistics: mean, median, mode, skew, kurtosis and standard deviation (SD). Winsteps uses the SD as the most meaningful way to compare distributions. Combine two very similar distributions (the common items SD of test A/SD of test B is near 1) by shifting the mean of one distribution to match the other distribution. A constant is added to or subtracted from each measure to put test B into the frame of reference of test A.

If the two distributions are not very similar, extreme items can be liberally discarded to obtain a better match for Winsteps in estimating Rasch model measures. This is not directly comparable to discarding values based on right mark counts using CTT. Counts and measures are not the same thing (see previous post).

Winsteps reports student raw scores in perfect alignment with student abilities, Table 17.1. But it reports item difficulties in a fuzzy array, Table 13.1. A range of item difficulty raw score counts can yield the same measure. Two difficult items can be worth the same as three easy items in measures.  


If the two distributions are still not very similar, they can be combined by both shifting the mean, as above, and by stretching or shrinking. The ratio obtained by dividing the common item SD for one test by the other is the required constant. Measures in one of the distributions are multiplied or divided by this constant to put them into the frame of reference of the other distribution.

When to add or subtract, or to multiply or divide, is determined by what activity you are engaged in (item calibration, test banking, cut score, or application) as well as how the two test score distributions match. Psychometricians tend to think along the line that they are sampling from one big population when calibrating items and when applying the standardized test. Many statistics are set up with the normal curve, the know-nothing curve (the curve obtained by marking the answer sheet without looking at the test), as the background reference. (This idea is mostly false in NCLB standardized testing where there is a strong demand for higher scores every year. The students of this year are, hopefully, better prepared than those of past years. They should not be members of the same population. If they are, there is no progress.)


If the higher scoring students on test B had been less able, they would have scored the same as those on test A. Also if the lower scoring test B students had been more able they would have scored the same as those on test A. So, in theory, adjust accordingly.


Several states have made the argument that they are making their tests more difficult. Therefore lower students scores should be increased to match those from earlier years (or the cut score should be lowered).

But application is more complicated than the above chart. There are more than just two outcomes. This is true using CTT or IRT methods. Because IRT measures are derived values (from both student right counts and item difficulty wrong counts) they do not maintain a direct relationship with counts (see item difficulty, Winsteps Table 13.1 above). The same student mark data can yield opposite effects using CTT or IRT methods. The following four outcomes must be considered fully within only one method at a time.


The two un-shaded outcomes result from the common items average scores not being in sync with the total test scores. This can be avoided by discarding data that leads to results that do not match the expectations of the Rasch model.

The two shaded outcomes make sense when calibrating and test banking from a common population. These two outcomes are open to question during application.

If there is reason to believe the benchmark test A and the application test B are really sampling the same population, then the given adjustment stands when test B yields both total and common item average scores higher than test A. If not, the application test has a significantly higher average test score than the benchmark test A, then lowering the test B scores or raising the cut score seems incorrect. We have two different populations. The current one has performed better than the previous one.

The same reasoning applies when test B yields both total and common item average scores that are lower than test A. The more difficult test results require increasing the student scores or lowering the cut score. But this makes little sense. Common items do not change in difficulty. Students change in ability. We are not sampling the same population. The current one is not performing as well as the previous one. If this trend were followed to the extreme, student scores would become adjusted higher or cut scores lower until randomly created results (mark the answer sheet without looking at the test) would pass most students. This is the end game for psychometricans, politicians, administrators and teachers when functioning at the lowest levels of thinking and there is little meaningful relationship between the test and the domain it is reported to be assessing.

Winsteps does an adequate job of item calibration, test banking, and equating (it has a zillion refinements that I do not know enough about to appreciate). How these are used is a matter of judgment on the part of those who control the assessment process. These people must be held to high professional standards by appropriate audits and transparency. A distinction needs to be kept in mind between the requirements of research, application, and natural experiments. NCLB assessments now span all of these.

A strong relationship needs to be made between the test and what it is assessing. A current example (developed to fill the entrepreneurial vacuum created by high school diplomas of questionable value) is the ACT WorkKeys test. What skills have students learned in high school that prepare them to do specific, well defined, tasks commonly needed in the workplace? The questions are presented as a sampling of select domains at all levels of thinking in Applied Mathematics, Reading for Information, and Locating Information. Doing well on the test is a prediction of success in the selected domains at all levels of thinking. Knowledge and Judgment Scoring (KJS) has similar properties: students, teachers and employers can know what can be trusted as the basis for further learning and instruction at all levels of thinking.

I have learned, in the last 12 months, that there is a difference between counting things and measuring them. Counting is measuring only if all items being counted have the exact same properties. This brings my audit of the Rasch model to a close. In the process, Winsteps has become a friend that adds finer detail to Power Up Plus (PUP) when using the Partial Credit Rasch Model.

Wednesday, July 13, 2011

Winsteps - Basic Relationships

                                                             29

Before proceeding with equating, it is important to have in mind just what is being equated, by Winsteps using item response theory (IRT), or by traditional, classic test theory (CTT).  Psychometricians, politicians, administrators, teachers, and students look at test data in different ways. Psychometricans are concerned with how well the data matches some ideal concept, the Rasch model for Winsteps, or a normal distribution. Administrators and politicians are concerned over average test scores.

Good teachers see how well individual students respond to instruction when students are free to report what they know, and trust, and what they have yet to learn. Students have a wide range of interests from the inattentive passive pupil to the self-correcting scholar. Multiple-choice test scores do a very poor job of reflecting the variation in student performance when only the right marks are counted. The scores produce a ranking that is still commonly accepted without question.

The measure ogive for a complete test represents a powerful relationship between student ability and item difficulty. Students with an ability equal to the same item difficulty have a 50:50 chance of marking a right answer all along this line. Easy questions require little ability. Difficult questions require high ability. With CTT, this relationship only occurs for an item with a difficulty equal to the average test score when marked by students with an ability also equal to the average test score. With Winsteps, this unique point is the zero point on the student ability and item difficulty measures scale. It transforms into an expected student score of 50%.

Winsteps sets the item difficulty measures for the three charted tests at zero measures. That means student ability measures are lower than item difficulty measures on an impossible test. Student ability measures are higher than item difficulty measures on a traditional classroom test.

Student ability measures are based on the relative difficulty of the items marked correctly. Item difficulty measures are based on the relative student ability to mark correctly (hence the cyclic math used to estimate measures). Each student receives an individualized ability estimated measure based on the interrelated average student and item performances. 


A measure is not the sum or average of counts. Counts make a variable look uniform when it is not: one point for each right answer to questions of variable difficulty (CTT). Measures assess the value of the variable being counted (IRT). You can buy melons of variable sizes at $2 each, by count, or you can buy melons at 10 cents a pound, by weight measure.  

Students who cannot read the test or understand the questions are placed in the impossible position of gambling for a passing score. On a four-option test, they receive a handicap of 25%, on average. A normal distribution around this point rarely produces a passing score. Even though the same relationship between student ability and item difficulty holds the full length of the ogive, that does not mean very low scores represent any meaningful measurement of student performance. The results of a randomly generated test at the 25% performance level are utter nonsense. Equating these scores to some higher level of performance does not make them any more meaningful.

Computerized adaptive testing (CAT) functions at the 50% performance level. It administers questions that closely match the ability of each student. This is very efficient. It takes less time and fewer items than when using a paper test. High ability students are not bothered with easy questions. Low ability students are not forced to come up with the “best answer” on items they have no idea of how to answer. Each student receives an individualized test based on the average performance of other students.

Knowledge and Judgment Scoring (KJS) also starts at the 50% performance level when knowledge and judgment are given equal weight. High ability students can zip through easy items and low ability students can skip impossible items. Both can yield high quality results: few if any wrong marks. With KJS each student individualizes the test to report what is known and what has yet to be learned (quantity and quality are combined into a test score). Each student receives an individualized test based on each student’s own judgment.

Both KJS and traditional right mark scoring (RMS) produce average classroom scores of 75%. The difference is that with KJS both the student and the test maker know what the student knows, and how well the student knows, at the time of the test and long afterwards. With RMS we only get a ranking increasingly contaminated with chance at lower scores. The same set of questions can be used on both with KJS and RMS to get a desired average test score. With the exception of KJS, the lower the quantitative test scores, the lower the quality of the results.

Score distributions subject to equating can carry far more information than the simple normal bell-curve. An hour test in a remedial general studies biology course often yielded four modes: A large mode centered at 60% from students enrolled pass/fail; a smaller mode at 75% from attentive passive pupils needing a C out of the course; a smaller mode at 90% who were self-correcting scholars; and a very small mode at 100%, who in later years were tested out with credit (if an A or B) the first week of the course. Classroom and standardized tests have different characteristics because they are designed to assess for different reasons. The classroom test monitors learning. The standardized test, when limited to right count scoring, is a ranking device that obtains only a small portion of the information available when using KJS, or as Bond and Fox (2007), Chapter 7, call it, the Partial Credit Rasch Model.
  

Thursday, June 16, 2011

PUP-IRT Winsteps Unexpectedness


#28
PUP-IRT cannot automatically create fully colored tables from the default settings of Winsteps. You must first run Winsteps and observe the ST. RES. results in Output Table 6.6. If the absolute value has not fallen below 1.5, then add UCOUNT= as suggested below:

UCOUNT=200   ;The default value is 50. You must reset to
            ;a larger value to color all MOST UNEXPECTED
                        ;(>2.0 ST. RES) and even larger to color all
                        ;LESS UNEXPECTED (1.5 - 2.0 ST. RES) listed
            ;in column five on Winsteps Table 6.6 in
                        ;Output Table 6. PERSON (row) fit order.
&END
1                        ;item labels
2

In this example, UCOUNT = 100 listed all the MOST UNEXPECTED, and UCOUNT = 200 listed all the LESS UNEXPECTED.

All students do not learn and retain specific knowledge and specific skills with equal ability. The unexpectedness colored on PUP Table 3c is an on-average value. About half of the students on this Fall88 test have an omit colored Most Unexpected. This in no way means that each of these students should have marked. It does say that, in general, it is most unexpected for a student with this ability, on-average, to omit (blue) a question with this difficulty, on-average. We cannot determine the specific reason each student omitted from PUP Table 3c.


PUP Table 3a, Mastery, Unfinished, and Discriminating, a test maker view of the test results, provides more information.


PUP Table 3b, Expected, Guessing, Misconception, and Discriminating, a test taker view of the test, splits the omits between Expected and Discriminating among higher scoring students. 

Tuesday, May 31, 2011

Power Up Plus CTT-IRT (PUP-IRT)

PUP version 5.20 combines Classical Test Theory (CTT) and Intem Response Theory (IRT) to color the unexpectedness of student marks in five PUP printouts.  Also download Ministep.* [On Windows 7, uncheck Hide File Extensions.]

Work Order: (in a folder named PUPIRT, for example)

   Create a PUP answer file (.ANS) or download  NURSE1.ANS.


   Create a Ministep answer file (.txt) or download Nurse1.txt.
   Run Ministep and save Table 6 as IRT.txt or download IRT.txt


   Run PUP-IRT in the folder named PUPIRT.

Ministep is easy to use after you select the few features you will need.
1.    Click Ministep to run the program.
2.    At the Ministep Welcome, click NO.
3.    Press Enter for Dialog Box:
4.    Find and select:                                                              Nurse1.txt.
5.    Press Enter for temporary file:
6.    Press Enter to analyze:
7.    Click Output Tables.
8.    Click 6. PERSON (rows): fit order
9.    Save Table 6 in the folder named PUPIRT as:             IRT.txt

PUP 5.20 and Winsteps are unlimited. Ministep is limited to 25 questions and 75 students. PUP 5.20 requires a file named IRT.txt for automatic loading and for analysis. (You can name the Ministep Table 6 file whatever you want but then you must find and select it.)
1.    Click PUP-IRT to run the program.
2.    Click Enable Content to activate macros (if asked).
3.    Click Add-Ins to expose the program tool bar.
4.    Click Import , find and select:                                        NURSE1.ANS
5.    Click Parse, find and select (if not automatic):              IRT.txt

The following combined CTT and IRT files are then colored:
1.    MUD                3a. Mastery, Unfinished, and Discriminating items.
2.    EGMD**        3b. Expected, Guessing, Misconception, and Discriminating Items.
3.    Guttman         3c. Sorted by Student Score and Item Difficulty.
4.    IDxItem          3d. Sorted by Student ID and Item Number.
5.    TopFive            9. Individual Pairings (presumptive cheating).

*   Linacre, J. M. (2011). WINSTEPS® Rasch measurement computer program. Beaverton, Oregon: Winsteps.com.
**EGMD only prints with Knowledge and Judgment Scoring (KJS) as only when students are permitted to report what they trust (understand and find useful as the basis for further learning) is this information available.

Wednesday, April 27, 2011

PCRM - Cheating

                                                       Chapter 26

Experience during the past few years with multiple-choice tests scored by only counting right marks has made it clear that cheating occurs at all levels from student to state house. The usual method for detecting this activity is to compare observations with probabilistic models. The down side of this approach is that the models are generally too simplistic to match the real world. Also, school administrators value “catching them in the act” (a very difficulty thing to do) far more than “statistics” applied to individual students.

An alternative is to make use of the information content in each student answer string. Answer strings can be matched by collating, filtering and sorting. Presumptive cheating is then a marked departure from the class norm. Confirmed cheating usually requires additional information that is accepted by students and administrators.

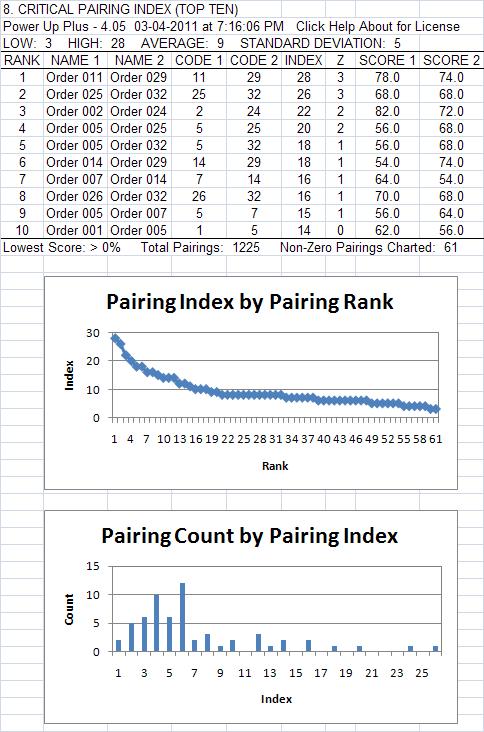
The PUP copy detector shows a suspect pair on Part 1&2 involving student 11 and 29 with a standardized index (Z) value of 3, a marginal level of detection. This individual pairing shows a string of 14 identical marks followed by strings of 2 and 7 identical marks. This is presumptive cheating.

The student counseling matrixes show identical strings within unfinished (-A@D@EE-) and within misconception and guessing (D@EE-A). No other of the fifty students marked in this fashion. Question 9 was flagged by Ministep as most unexpected right. Only two students with the lowest scores shared this classification.

I would not call this a confirmed case of copying, as six of the seven identical pairs were non-critical, that is the identical wrong marks were too common on the test. In my judgment, this pair did not fail the test for independent marking. Failure would require additional information. There is also no noticeable marked departure from the class norm.

A record of presumptive cheating is easy to keep on mark matrixes sorted by student ID and question number, PUP 3b, or by score and difficulty, PUP 3c. Answer sheets were coded with three spaces each, for test number and seat number. Students filled in their three-digit student number. This information generally permitted confirming cheating, without resorting to multiple test forms (a negative, time wasting, procedure). Relying on their written record (answer sheets), just as scientists do, modeled the ethics of science as these students explored and developed their ability and desire to make sense of biological literature for the rest of their lives. (On the Internet, it is even more important to have formed the habit of questioning and confirming the information encountered.) 

The most successful classroom policy I used to manage copying was to clearly state that answer sheets would be checked for cheating to protect honest students. Any answer sheet that failed the check would receive a score of zero. I would help any student who wanted to protest this decision to student affairs (no student every protested, which was, in itself, a further confirmation of cheating). Two students were detected twice over a nine-year period. They readily admitted copying but were both unhappy with themselves over finding their “fool proof” methods in other courses did not work here.


Wednesday, April 20, 2011

PCRM - Guessing

                                                              Chapter 25

The Rasch model does not include guessing. This does not make it go away. Multiple-choice, by design, has a built in average random guessing score of one part for the printed set of answer options. Active scoring starts at 25% for 4-option questions scored by counting right marks. This scores and rewards the lowest levels of thinking. Active scoring starts at 50% for Knowledge and Judgment Scoring where higher levels of thinking are assessed and rewarded. If a student elects to mark all questions, both methods of scoring, included in PUP, yield the same score. The two methods of scoring respond the same to guessing.

Knowledge and Judgment Scoring, however, gives students the responsibility to learn and to report what they trust they know and can do. It is one form of “student-centered” instruction. This is critical in developing high quality self-correcting students, and as a result, high scoring students.

Five guessing items were found on Part 1&2 and six on Part 3&4 of the biology fall 88 test. These are items that fewer students, than the average score on the test, elected to mark, but less than that portion who marked, were right. A few students believed they knew but they did not know.  

The four [unfinished] items on Part 3&4 were also among the six guessing items. Most of the Ministep “most unexpected right responses” (dark blue) occurred on these items on Part 1&2 and 3&4. Are they guessing (chance or good luck) or just marking error that also occurs among the other groups of items?

Assuming that the most unexpected responses involve carelessness, guessing, and marking error, these then play a small part in determining a student’s score. The rate tends to increase as student performance decreases. Many unexpected wrong and right answers tend to occur in pairs. One cancels the effect of the other. Only consistent analysis is required to obtain comparable results.

If I interpret the above correctly, the partial credit Rasch model (PCRM) can ignore guessing in estimating person and item measures. However, a teacher or administrator cannot ignore the active starting score of a multiple-choice test in setting cut scores. A cut score set a few points above the range of random guessing is a bogus passing standard even if the test contains “difficult” items.


Thursday, April 14, 2011

PCRM - Misconception

                                                                 Chapter 24

Knowledge and Judgment Scoring allows students the option of reporting what, in their own judgment, they know, can do, and find meaningful and useful. This generates four options instead of the usual two (right and wrong) obtained from multiple-choice items by the traditional count of right marks.

A misconception is a question that most students believe they know a right answer to, and mark, when in fact they do not know (more students, than the average score on the test, elected to mark, but less than that portion who marked, were right). Only one item was flagged as a misconception, item 6, on both halves of the biology fall 88 test. This can be compared to four on an earlier test.

Top students who rushed through the test marked “A” as a “most unexpected wrong response” on item 6 on Part 1&2. Other students gave a mixed response on Part 1&2. Only two top students who took their time marked “A” on Part 3&4. Most of the remaining students marked “A” wrong on Part 3&4. This observation gives rise to several stories.

Did top students in a hurry pick the same answer as lower scoring students who took their time? Did students functioning at higher levels of thinking and taking their time reason out the correct answer?  Is this just sampling error?

Misconceptions make for good class discussions. Lectures seem to have little effect on changing student misconceptions. One misconception question repeated in several bi-weekly exams stabilized by most students omitting. The one thing they did know was that they did not understand something that would allow them to trust marking an answer to the question correctly (nor did they have in mind a meaningless right answer that matched an option on the question as the answer options were not always the same and were always randomized).

The combined report from Ministep and PUP opens a new window of inquiry into the behavior of students and test items. In my experience, these student-counseling matrixes provided a better insight into how a class and students were performing than reading “blue book” essays. Winsteps adds predictive measures to otherwise descriptive classroom data.